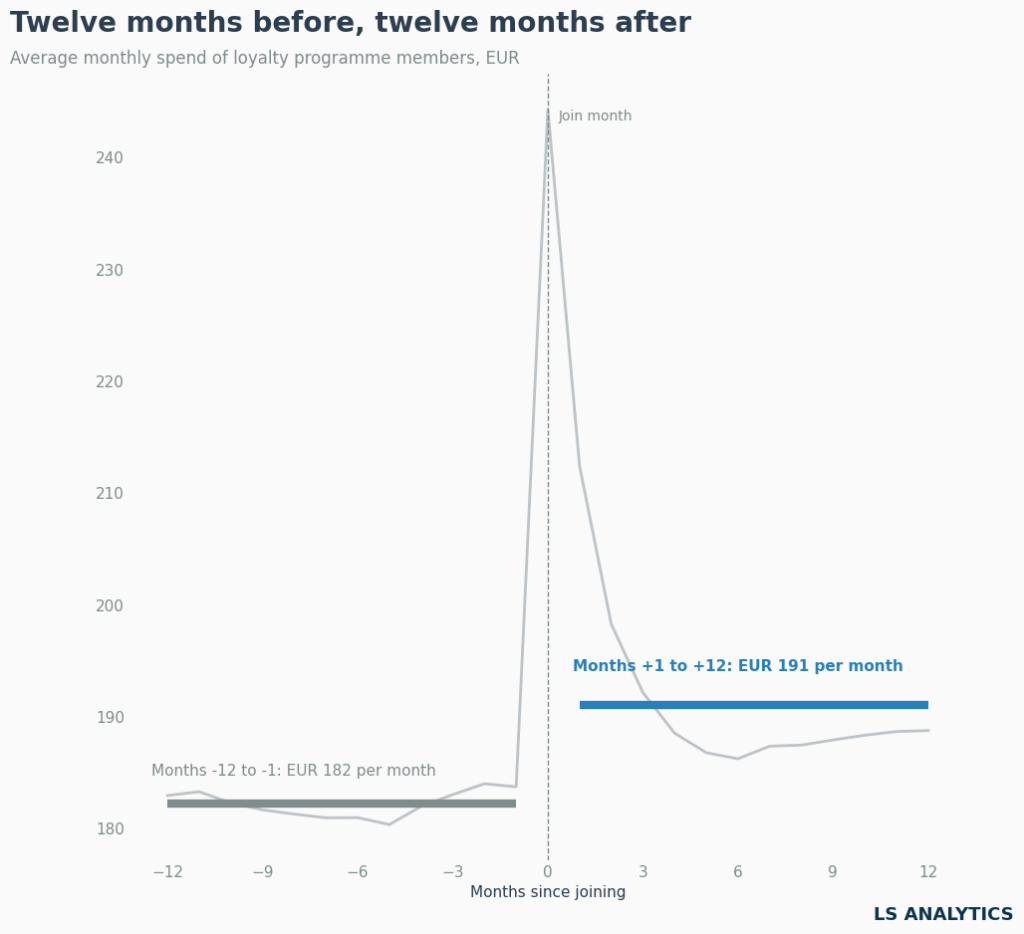
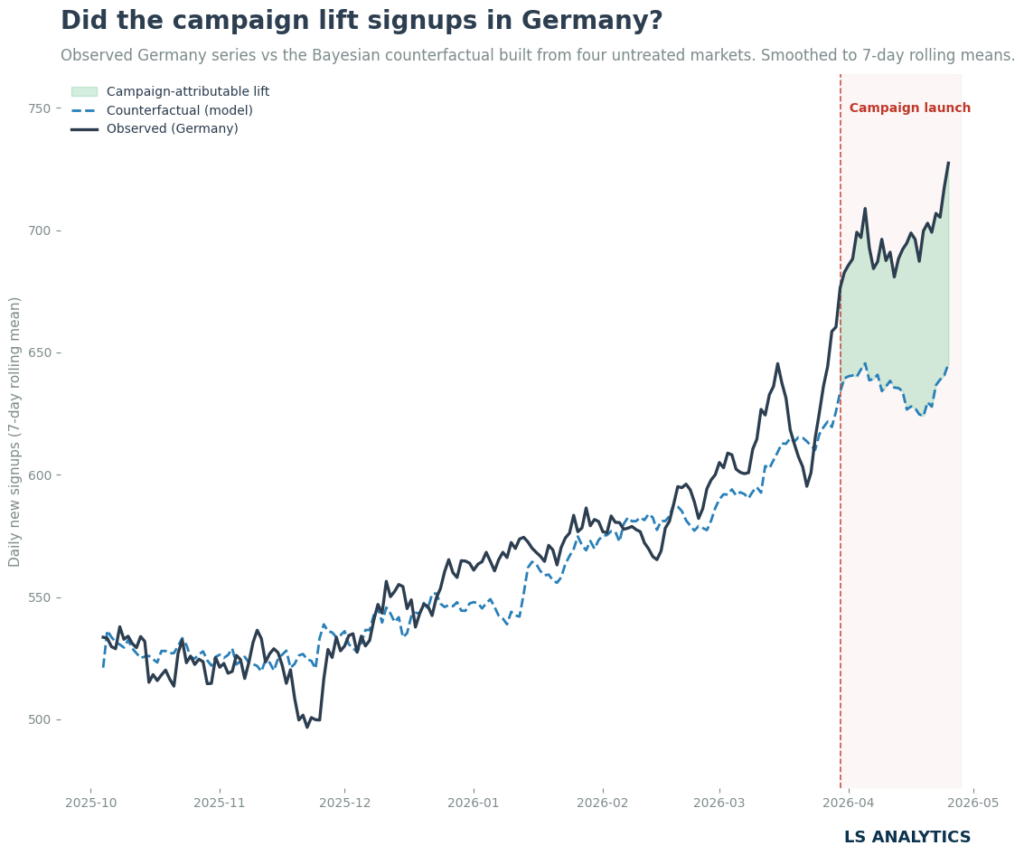
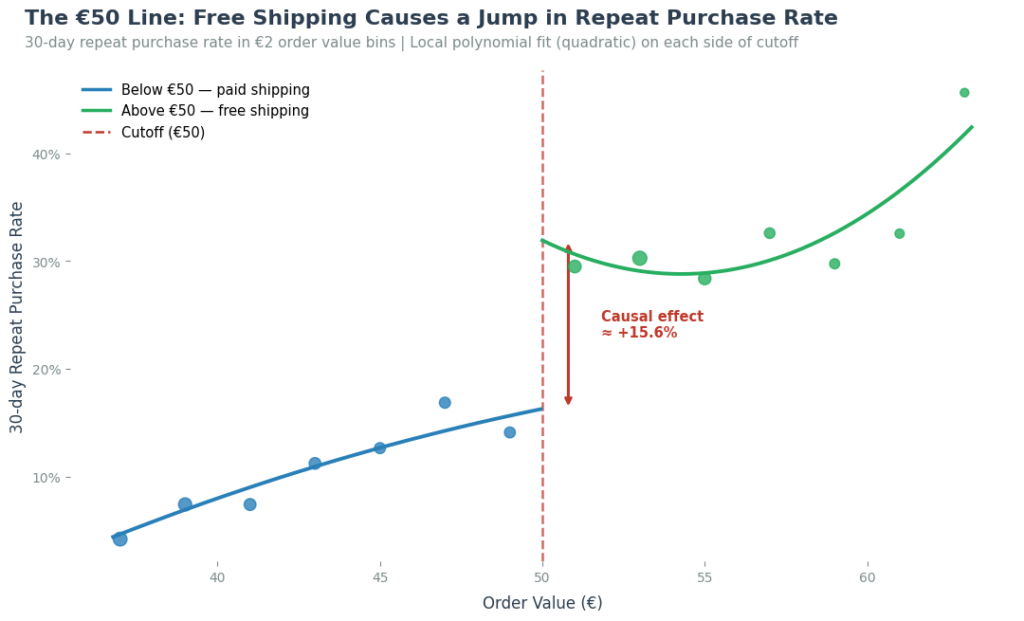
In the world of marketing, deciding which customers to target with specific promotions can feel like a never-ending puzzle — especially when budgets are constrained and resources are limited. This article aims to shine a light on that challenge using causal machine learning and, more specifically, uplift modelling.
Uplift modelling is a specialised approach that estimates how a treatment or intervention (e.g., a discount or advertisement) causally affects each individual’s outcome. Rather than focusing on average effects, it highlights each person’s incremental response to the treatment. This capability makes it especially valuable in marketing, healthcare, and policy-making, where pinpointing who benefits from an intervention can lead to more cost-effective, targeted strategies.
Although uplift modelling is not entirely new to causal inference, recent developments have made the framework more structured and practical. In this article, we explore how meta-learners can reveal deeper, more actionable insights than traditional machine learning alone, offering a powerful way to prioritise and optimise promotional efforts for maximum impact.
Uplift modelling vs traditional machine learning
The main goal of traditional machine learning is to predict specific outcome variable values based on the list of features. Uplift modelling differs because it aims to estimate the causal effect of a specific action.
Uplift modelling has many applications, but the most common ones come from business. Imagine we are marketers who want to run a discount program to increase revenue. We could make such a program available to our entire customer base, but it could waste resources. Why offer discounts to someone who would have used our product without it? The uplift modelling comes to the rescue in precisely such a setting.
The question we want to ask while applying uplift modelling is very straightforward: What is the effect of a given treatment on the individual customer? We are not interested in the average treatment effect, but we want to estimate the potential treatment effect at the individual level.
One can ask why we can’t estimate such an effect using standard machine learning techniques. We can’t apply them blindly, as traditional machine learning focuses on prediction—we would predict sales (or any given outcome) given a set of features.
In uplift modelling, we want to predict the incremental impact on an individual outcome. For example, how a given promotional activity will impact a specific individual.
This difference is subtle but easier to discover when we apply uplift techniques. We will still use familiar machine learning algorithms adapted to tackle the uplift problem.
Uplift modelling as the causal inference tool
Before we practice, it helps to think about uplift modelling from a causal inference perspective. It will help me position this tool correctly and understand it better.
The main goal of uplift modelling is to estimate the Conditional Average Treatment Effect (CATE). It is a fancy term for assessing the individual effect of the treatment on each customer.
We want to know what would have happened if someone had received treatment and compare it with what would have happened if someone hadn’t.
The difference between those two states gives us the CATE. And CATE is the uplift score at the customer level. We want to target with promotional activities only customers with positive CATE, those for whom the treatment would have a positive effect.
However, each customer can receive only one treatment at a given time. Here, we enter the fundamental problem of causal inference. We can never observe both outcomes for the same individual at the same time.
Let’s break it down:
- If you send someone the email campaign, they either buy or don’t buy the product.
- But what if you didn’t send the email? You’ll never know for sure what the customer would have done.
This “what-if” scenario is called the counterfactual, and it’s always missing in reality.
That’s where uplift modelling comes into play. By applying uplift modelling tools properly, we can use the models across the entire group of customers we want to target. The model helps select only those customers for whom the treatment effect will be positive, which should lead to a much better return on investment from promotional activities.
Practical scenario
Let’s switch from theory to practical application. As a marketing manager for an e-commerce company, we aim to increase subscriptions to a free delivery program (similar to Amazon Prime). However, instead of offering a discount to all customers, we strive to target only those who wouldn’t subscribe without the discount while avoiding unnecessary discounts for those who would subscribe anyway.
To achieve this, we will implement uplift modelling. To ensure valid uplift modelling, we will run a randomised trial where customers are split into two randomly selected groups:
- Treatment — Receives a discount for the subscription.
- Control — Does not receive a discount.
Randomisation ensures that both groups are similar apart from receiving the treatment. This helps ensure we measure the discount effect on subscriptions, since there are no other confounding factors between the two groups.
After running the experiment, we can measure the effect of a discount on the subscription at the aggregate level. Many A/B tests end here, but we will go one step deeper. We will use the data from this A/B test to train the uplift model.
By training on experimental data, the model will learn how different customer attributes correlate with their likelihood of being persuaded by the offer. It will enable us to distinguish four commonly described segments of customers in the uplift literature:
- Persuadables: Customers who subscribe only when given a discount.
- Sure Things: Customers who would subscribe regardless of a discount.
- Lost Causes: Customers who wouldn’t subscribe, even with a discount.
- Sleeping Dogs: Customers who are less likely to subscribe when given a discount.
Naturally, we would like to target only the Persuadables group. The other segments are those for whom discounts would be detrimental to the business strategy.
Once the uplift model is trained and validated, it is applied to new customer data — customers who were not part of the original experiment but are potential targets for future marketing efforts.
By feeding new customer profiles into the trained model, we obtain a personalised uplift score for each customer, estimating how much the discount influences them. Based on this inference step, we will select only the customers with positive uplift scores, and promotional activities will target them.
This uplift modelling framework ensures that the team focuses the budget on high-impact customers, increasing overall profitability and improving customer acquisition efficiency.
Data preparation
We will simulate the dataset to showcase the uplift modelling application. Since most uplift applications occur in business settings, we can’t obtain such a practical dataset. Preparing such data usually takes a long time, and I’d like to focus on the conceptual applications of uplift modelling.
What’s essential is having access to the group of customers randomly selected as the control group. So we can estimate the uplift effect by comparing the two groups.
def simulate_free_delivery_subscription_extended(n_samples=5000, seed=42):
    """
    Simulate data for a randomized trial measuring the effect of a discount on
    subscription to a free delivery program,
    with extended demographic features.
    Parameters
    ----------
    n_samples : int
        Number of observations (customers) to generate.
    seed : int
        Random seed for reproducibility.
    Returns
    -------
    df : pd.DataFrame
        Simulated dataset with user features (including extra demographics),
        a treatment indicator, and a subscription outcome.
    """
    np.random.seed(seed)

    age = np.random.randint(18, 70, size=n_samples)
    purchase_freq = np.random.poisson(lam=2, size=n_samples)
    avg_spend = np.round(np.random.gamma(shape=2.0, scale=50.0, size=n_samples), 2)

    gender = np.random.binomial(1, p=0.5, size=n_samples)
    regions = np.random.choice(['Urban', 'Suburban', 'Rural'],
                               size=n_samples,
                               p=[0.5, 0.3, 0.2])
    treatment = np.random.binomial(1, 0.5, size=n_samples)

    region_effect_map = {'Urban': 0.3, 'Suburban': 0.2, 'Rural': 0.0}
    region_effect = np.array([region_effect_map[r] for r in regions])

    log_odds_baseline = (
        -4.0
        - 0.02 * age
        + 0.5  * purchase_freq
        + 0.01 * avg_spend
        + 0.1  * gender
        + region_effect
    )

    treatment_effect = 1.0
    log_odds = log_odds_baseline + treatment * treatment_effect
    prob_subscription = expit(log_odds)

    subscription = np.random.binomial(1, prob_subscription)

    df = pd.DataFrame({
        'age': age,
        'purchase_freq': purchase_freq,
        'avg_spend': avg_spend,
        'gender': gender,
        'region': regions,
        'treatment': treatment,
        'subscription': subscription
    })

    return df
The script simulates customer data to evaluate a marketing campaign’s effectiveness using uplift modelling. It generates a synthetic dataset representing an e-commerce scenario where customers are randomly split into treatment (receiving a discount offer) and control groups.
The dataset includes customer demographics (age, gender, region) and purchasing behaviours (purchase frequency, average spend). We calculate each customer’s likelihood of subscribing based on these features, with the discount’s effectiveness varying across individuals.
The final dataset we will use looks like the one below, with a treatment column indicating whether the customer was randomly selected for the discount program and the outcome stored in the binary subscription column.

Before calculating uplift, we must preprocess the dataset to make it suitable for modelling. We split the data into training and test sets and transform the categorical region column into a numerical type using one-hot encoding.
Uplift modelling requires splitting not only the features and outcome, as in traditional machine learning, but also the treatment column.
X = df.drop(columns=['subscription', 'treatment'])
T = df['treatment']
y = df['subscription']

X_train, X_test, T_train, T_test, y_train, y_test = train_test_split(
    X, T, y, test_size=0.2, random_state=42
)

encoder = OneHotEncoder(drop='first', sparse_output=False, handle_unknown='ignore')

X_train_encoded = encoder.fit_transform(X_train[['region']])
X_test_encoded = encoder.transform(X_test[['region']])

encoded_cols = encoder.get_feature_names_out(['region'])
X_train_encoded_df = pd.DataFrame(X_train_encoded, columns=encoded_cols, index=X_train.index)
X_test_encoded_df = pd.DataFrame(X_test_encoded, columns=encoded_cols, index=X_test.index)
s
X_train_final = pd.concat([X_train.drop(columns='region'), X_train_encoded_df], axis=1)
X_test_final = pd.concat([X_test.drop(columns='region'), X_test_encoded_df], axis=1)
Uplift calculation
There are multiple ways to calculate uplift and to discover the CATE. Most rely on machine learning algorithms, combined cleverly to suit the specificity of the uplift problem, i.e., the presence of the treatment variable.
I propose focusing on uplift calculations by applying the meta-learners family of approaches. The name might sound intimidating, but it allows us to understand uplift straightforwardly. Meta-learners are not separate algorithms but conceptual frameworks we can apply to discover the uplift effect.
We will use the scikit-uplift library, tailored for uplift modelling, for simplicity and reusability. Other libraries can also address this challenge, which we will explore in the following articles.
Evaluation of the uplift models
Before we run uplift models, let’s discuss how to assess their performance. Evaluating the uplift models differs from evaluating the traditional ML methods. We can’t simply focus on measuring the models’ accuracy or other conventional machine learning metrics, because the main focus here isn’t prediction—it’s identifying the true uplift effect.
We want to measure how effectively the model identifies individuals whose behaviour changes when offered treatment versus control.
Two popular metrics for this are the Qini Curve and its associated Qini AUC (Area Under the Qini Curve). The Qini Curve sorts individuals by predicted uplift (from highest to lowest) and plots the cumulative difference in outcomes between treated and untreated segments. A higher area under this curve indicates that the model more accurately distinguishes those influenced by the treatment.
We can break down construction of this curve into the following steps:
- Rank by Predicted Uplift
- First, each individual is assigned an uplift score
- Then sort all individuals from highest predicted uplift to lowest.
2. Partition the Scored Population into percentiles by the sorted uplift score
3. Compute Incremental Outcome
- For each percentile, calculate the number of incremental positive outcomes in the treatment group compared to the control group, adjusting for group sizes.
4. Plot the Cumulative Difference
- On the x-axis: the fraction of the population (from 0% to 100%).
- On the y-axis: the cumulative incremental outcome (e.g., additional conversions)
The resulting curve shows how effectively the model identifies those who benefit from treatment. A steeper initial slope and a higher peak mean the model better pinpoints the most persuadable individuals first.
S-learner
The simplest model we can use in uplift modelling is the so-called S-Learner. It uses a single machine learning method and all existing data (including treatment status) as inputs.
In the subscription discount campaign, the S-Learner trains a single machine learning model that takes customer features and the treatment indicator (whether the discount was offered) as inputs.
For each meta-learner, we can choose different base machine learning techniques. This explains the name of the framework, as we rearrange traditional machine learning techniques for the uplift modelling setting.
Technically, there are no limitations in selecting the models used for training. In the S-Learner, we choose only one model, but in more complex meta-learners, we can combine different machine learners for different tasks.
To estimate the uplift for a particular customer, the S-Learner predicts two outcomes: one assuming the customer was offered the discount and the other assuming they were not.
The difference between these two predictions indicates how much the discount is expected to increase (or decrease) the subscription probability for that customer. This approach is straightforward and efficient for problems in which treatment can be treated as an additional feature in a supervised learning setup.
We can break down applying the S-learner using the following steps:
- Train a Single Model: Fit a single machine learning model (e.g., Gradient Boosting) on the training set, treating treatment as just another feature.
- Predict Potential Outcomes: For each individual in the test set, predict their outcome twice — once assuming treatment = 1 and once assuming treatment = 0
- Compute Uplift: Subtract the predicted probability of no treatment from the predicted probability with treatment. The difference represents the model’s estimate of how much the discount influences that specific individual’s likelihood of subscribing.
Applying the S-learner using the scikit-uplift library is very simple. We can do it using a few lines of code.
s_learner = SoloModel(
    estimator=GradientBoostingClassifier(n_estimators=100, random_state=42),
    method='treatment_interaction'
)

# Fit the model on training data
s_learner.fit(X_train_final, y_train, T_train)

uplift_preds = s_learner.predict(X_test_final)
We will also evaluate the uplift obtained using the qini curve described above. The final AUC of the model will be used as our benchmark to assess its efficiency:

T-learner
The T-Learner approach estimates uplift by training two separate predictive models: one for the treatment group and one for the control group. Each model learns the relationship between customer characteristics and the outcome.
To estimate the individual treatment effect for a new customer, we use the appropriate model to predict their probability of subscribing under the treatment condition and another model to predict their likelihood of subscribing under the control condition.
The difference between these two probabilities indicates the estimated uplift — the extent to which the treatment (discount) is expected to influence that particular individual’s likelihood of subscribing.
To summarise:
- Train Two Models
Train one machine learning model (e.g., a Gradient Boosting classifier) on the treatment group to learn the probability of subscription given treatment and another model on the control group to learn the probability of subscription without treatment. - Apply Both Models to New Data
For any new customer, run their features through both models — one trained for treatment, one for control. - Compute Uplift
Subtract the control prediction (probability of subscription with no discount) from the treatment prediction (probability of subscription with a discount). This difference is the estimated uplift for that individual.
t_learner = TwoModels(
    estimator_trmnt=GradientBoostingClassifier(n_estimators=100, random_state=42),
    estimator_ctrl=GradientBoostingClassifier(n_estimators=100, random_state=42)
)

t_learner.fit(X_train_final, y_train, T_train)

uplift_preds_t = t_learner.predict(X_test_final)

Comparison
Which of the analysed models showcase the better performance? Let’s compare their Qini curves one more time.

Based on the provided Qini curve comparison chart, the T-Learner (AUC = 0.1328) slightly outperforms the S-Learner (AUC = 0.1297). Although the performance difference is subtle, the T-Learner consistently remains above both the S-Learner and the random targeting baseline, particularly in the middle and upper segments of the ranked population.
This indicates that the T-Learner is marginally better at identifying individuals who would truly benefit from the treatment (discount), thus making it the preferred model for targeted marketing campaigns in our case.
Applying the model
The crucial part of developing any machine learning model is its application in practice. In uplift modelling, we want to build the best possible model and apply it in reality. How can we do it for new customers who were not part of our training experiment?
When deploying an uplift model to new, unseen customers, we can score each individual by running their features through the trained model. The model outputs a predicted uplift — an estimate of how likely each person is to subscribe if offered the discount versus if not offered. We can then rank new customers from the highest predicted uplift to the lowest.
After ranking new instances, we must decide on a cutoff — for example, the top 20% of customers by predicted uplift. These are the individuals the model believes are most likely to change their behaviour because of the discount.
We will send our marketing offers only to those above the cutoff. Doing so maximises incremental gains (i.e., additional subscriptions that wouldn’t have happened otherwise).
Customers with low or negative predicted uplift would likely either subscribe anyway (no discount needed) or not respond to the discount. Hence, we can increase the ROI of marketing activities by omitting them in campaigns.
This approach focuses marketing resources on customers whose actions the promotion is most likely to change. As a result, the cost of providing discounts to people who would have subscribed anyway (or won’t respond regardless) is minimised, improving the campaign’s overall ROI. This is a clear example of how machine learning applications and causal inference can improve performance in a specific business area.
Summary
This article offered a concise look at uplift modelling through the lens of causal inference, highlighting how causal machine learning can guide more strategic, data-driven decisions. While we merely scratched the surface of this broad field, we hope it has sparked your interest in how these methods can transform business practices.
Looking ahead, our forthcoming articles will delve deeper into causal AI, uncovering more advanced techniques that bridge traditional machine learning with the rich world of causal inference.
References
- Hansotia, B. & Rukstales, B. (2002). “Incremental Value Modelling.” Journal of Direct Marketing 16(3): 23-34.
- Künzel, S. R., Sekhon, J. S., Bickel, P. J. & Yu, B. (2019). “Meta-Learners for Estimating Heterogeneous Treatment Effects Using Machine Learning.” Proceedings of the National Academy of Sciences 116 (10): 4156-4165.
- Gutierrez, P. & Gérardy, J-Y. (2021). “Uplift Modelling Methods.” Tutorial slides, Uplift Workshop. upliftworkshop.ipipan.waw.pl
- scikit-uplift (sklift) Documentation – Python package for uplift modelling (metrics, models, visualisations). uplift-modeling.com
- CausalML Docs – Detailed user guide & meta-learner examples. causalml.readthedocs.io
- scikit-uplift User Guide – “Essentials of Causal Inference & Uplift Modelling.